Testing hypotheses

Research Skills — Week 6

Recap

  • The null world
  • Interpret a t-test
  • Assumptions
  • Check your assumptions
  • The base rate fallacy
  • Plan your test
  • Wrap-up

Where we are

  • Week 3: the logic of hypothesis testing (conceptual)
  • Week 5: experimental design, controls, confounders

This week: the formal machinery. How do you tell a real difference from a fluke?

And then you’ll learn why the answer can mislead you.

Questions?

Submit questions:

PollEv.com/geol

text geol to 07480 781235

The null world

  • Recap

🎓💻 Concept block 1

  • Interpret a t-test
  • Assumptions
  • Check your assumptions
  • The base rate fallacy
  • Plan your test
  • Wrap-up

Is the difference real?

Boreholes in the Stainmore Formation run hotter, on average, than boreholes in the Whin Sill.

“Is this difference larger than we’d expect by chance?”
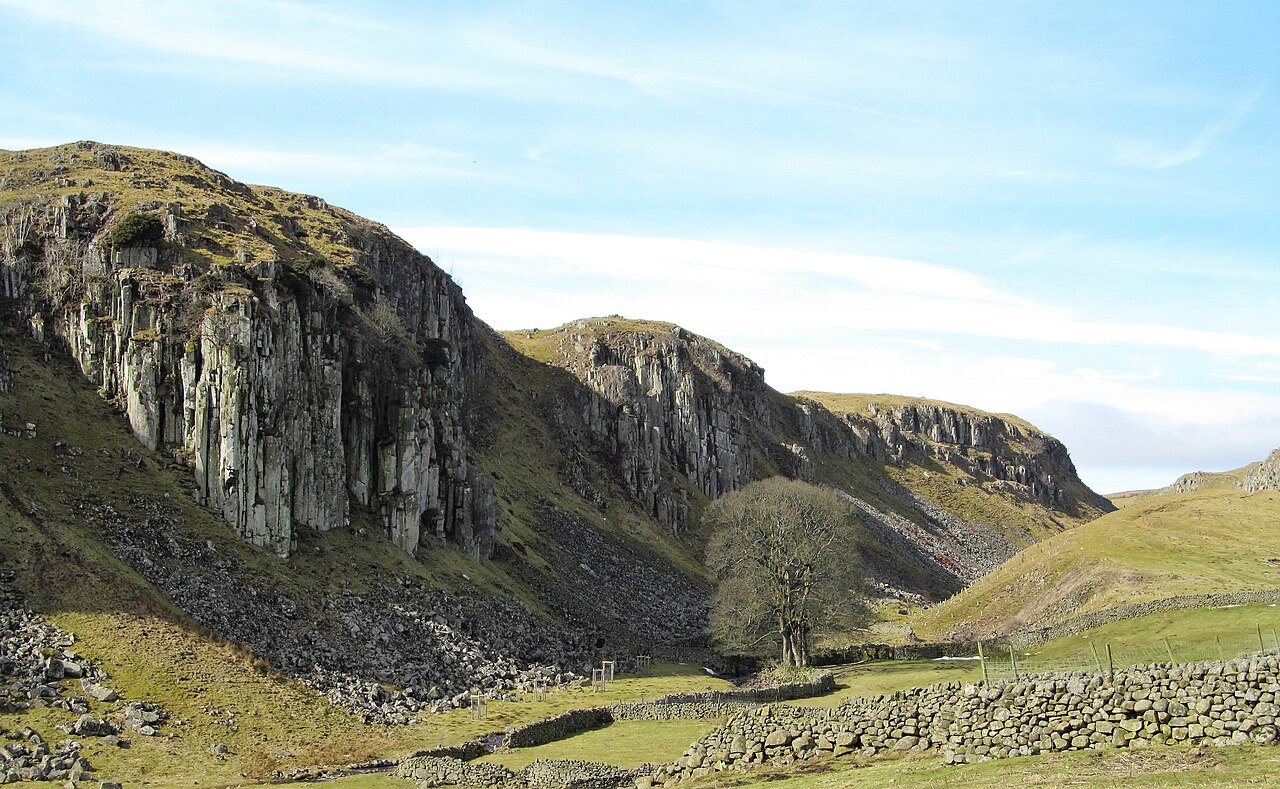
Grey cliffs of columnar dolerite rising above scree and drystone walls in a green valley.

The Whin Sill at Holwick Scars, Teesdale.
Gordon Hatton / Geograph, CC BY-SA 2.0

Five steps, every test

  1. Measure δ — the one number you care about. Here: Stainmore’s mean temperature minus Whin Sill’s.
  2. Build a null world — a world where δ really is zero. Simulate it: shuffle the formation labels, recompute δ, repeat.
  3. Drop your δ into it. Does it look at home?
  4. Count how often the null world makes a δ at least as extreme. That fraction is the p-value.
  5. Decide, against a standard you set before you looked.

A world where formation doesn’t matter
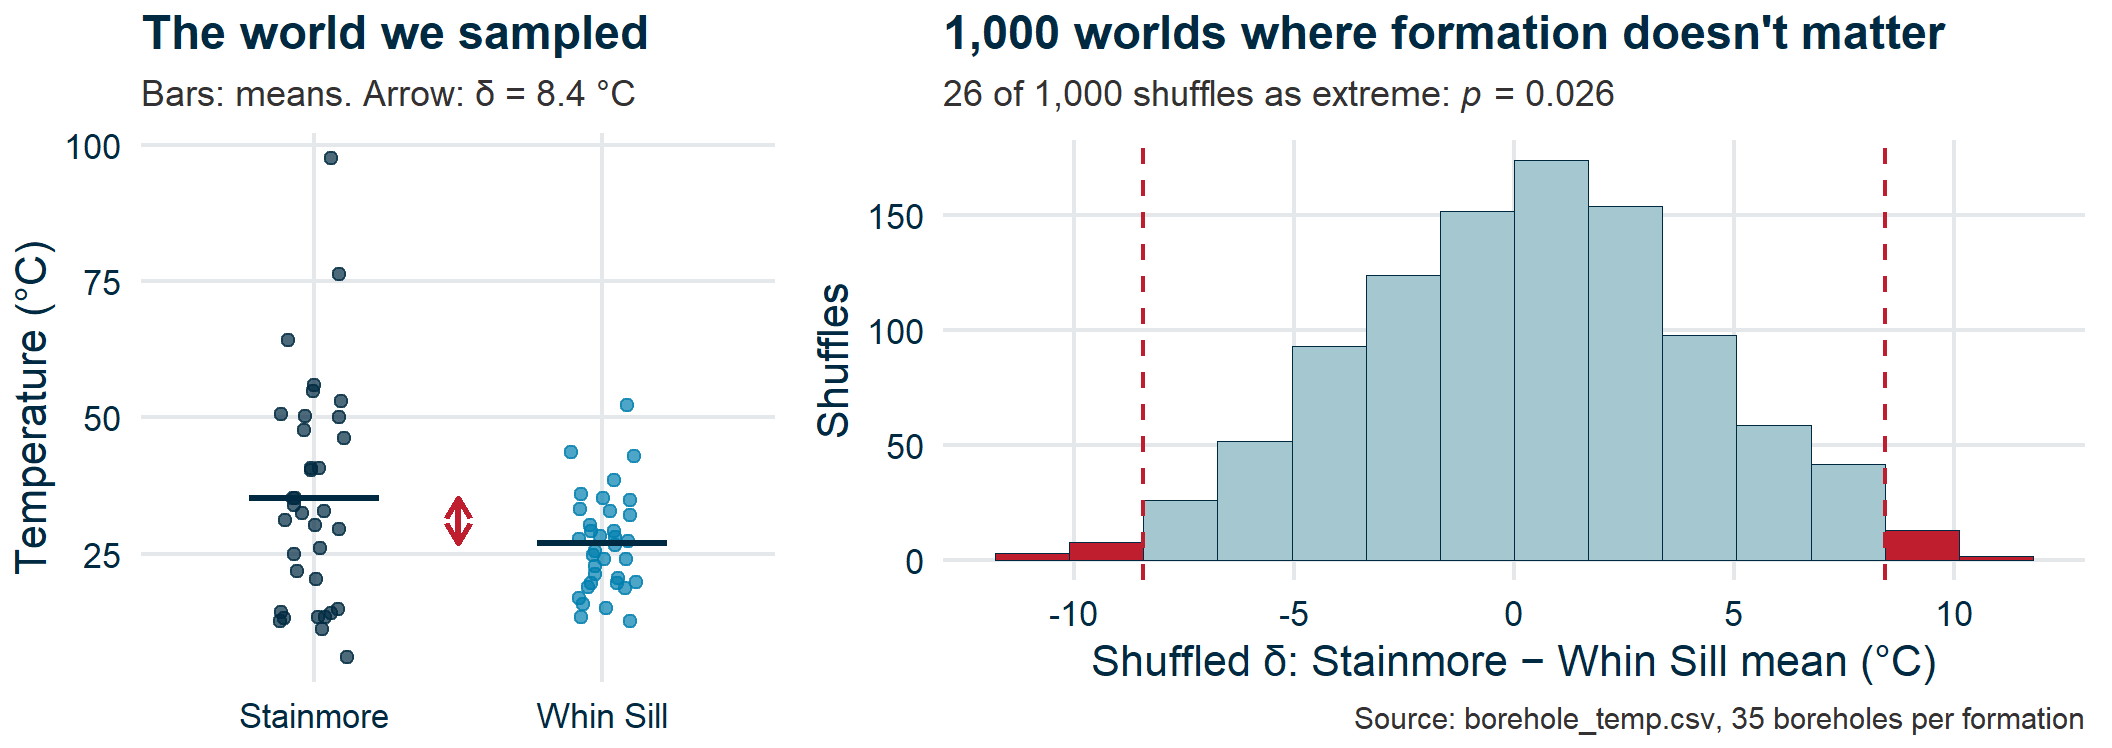
Two panels. Left: borehole temperatures as dots for the Stainmore and Whin Sill formations, with each formation's mean as a bar and a red arrow marking the 8.4 degree difference between them. Right: a histogram of the difference in means from 1,000 random shuffles of the formation labels, centred on zero and spanning about minus 11 to plus 11 degrees. Dashed red lines mark minus and plus 8.4; the few bars beyond them are red. 26 of the 1,000 shuffles are that extreme, p = 0.026.

w06-null-world.R · After Heiss (2026), Null worlds

Build the null world

What would the null world be?

For each claim, how would you build a world where it is false?

  1. Wind farms in Scotland run at a higher capacity factor than wind farms in Wales.
  2. Boreholes drilled after 2000 read warmer than older ones at the same depth.
  3. Monitoring wells downstream of a quarry have more sulphate than wells upstream.

This is a t-test

A t-test asks the same question with a formula, instead of a shuffle:

  1. Assume no difference: the null world (the null hypothesis)
  2. Calculate how far apart the means are, relative to the variability (→ t-statistic)
  3. Ask: if there were really no difference, how often would we see a t this extreme? (→ p-value)

Live demo

Reading the output

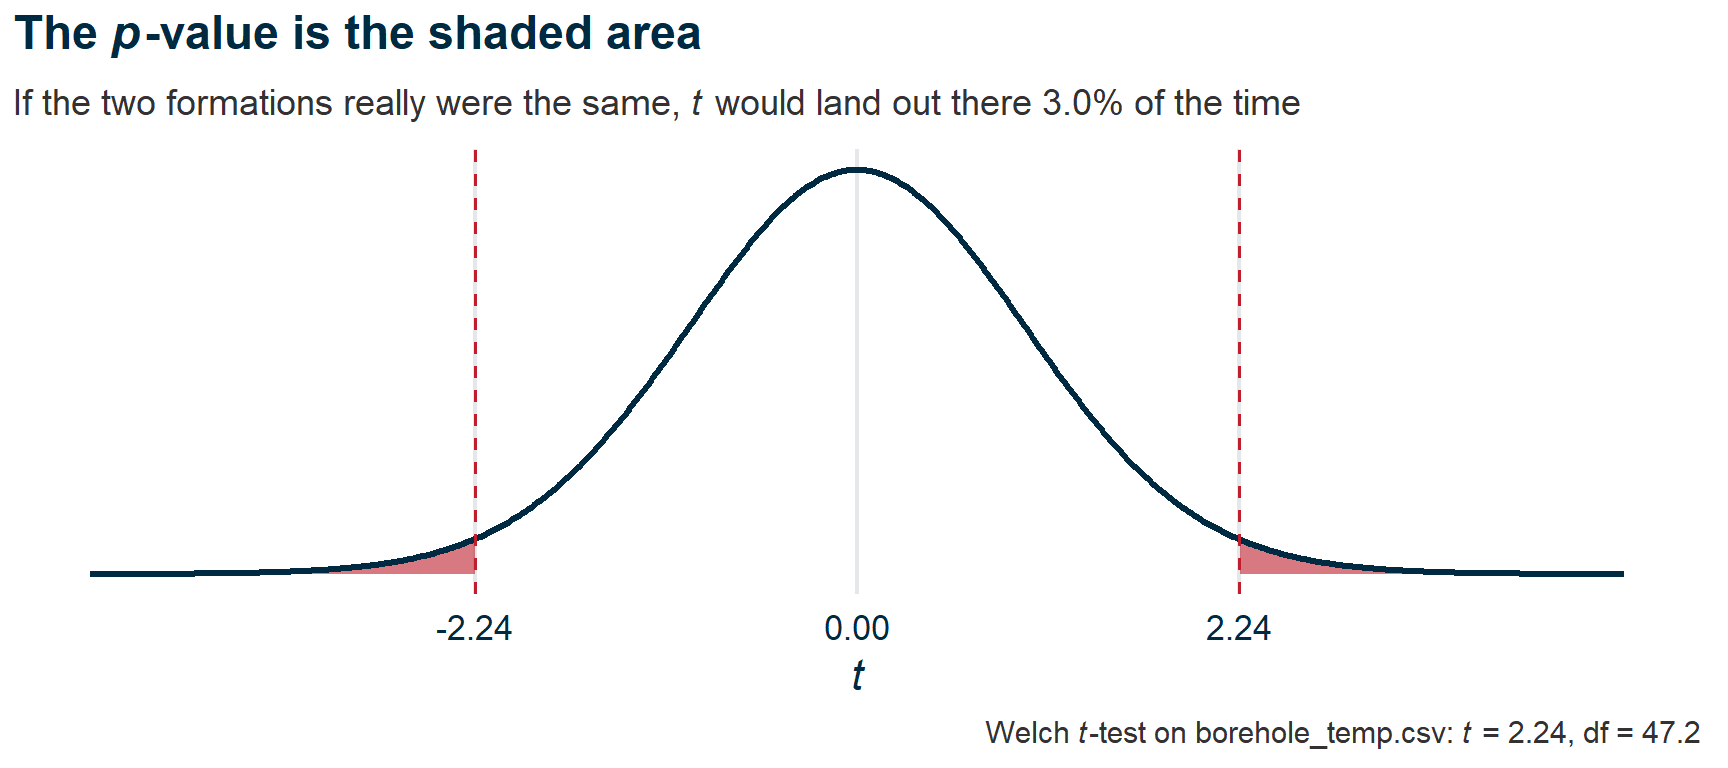
t = 2.24, df = 47.2, p-value = 0.030
95% CI: [0.86, 15.97]
Element Meaning
t-statistic How many SEs apart the means are
p-value How surprising, in the null world (where H₀ is true)
95% CI Plausible range for the true difference

What “how often” means

A t-distribution curve with dashed lines at minus 2.24 and 2.24 and the two tails beyond them shaded. The shaded slivers are 3% of the total area under the curve.

Interpret a t-test

  • Recap
  • The null world

💬✏️ Exercise 1

  • Assumptions
  • Check your assumptions
  • The base rate fallacy
  • Plan your test
  • Wrap-up

Write one sentence

I’m showing you R output from a t-test.

Write one sentence interpreting this result for a policy audience.

Then we’ll compare.

A common mistake

“p = 0.03 means there’s a 3% chance the null is true.”

Wrong. But extremely common. We’ll come back to this.

Assumptions

  • Recap
  • The null world
  • Interpret a t-test

🎓 Concept block 2

  • Check your assumptions
  • The base rate fallacy
  • Plan your test
  • Wrap-up

Every test rests on assumptions

For the t-test:

  1. Independence — observations don’t influence each other
  2. Normality — data within each group are roughly normal
  3. Equal variance — groups have similar spread (Student’s t; Welch’s t relaxes this)

How to check

Assumption Check
Normality Histogram, QQ plot, shapiro.test()
Equal variance Side-by-side points or violins, Levene’s test
Independence Think about the study design

When assumptions are violated

A skewed variable can produce misleading p-values.
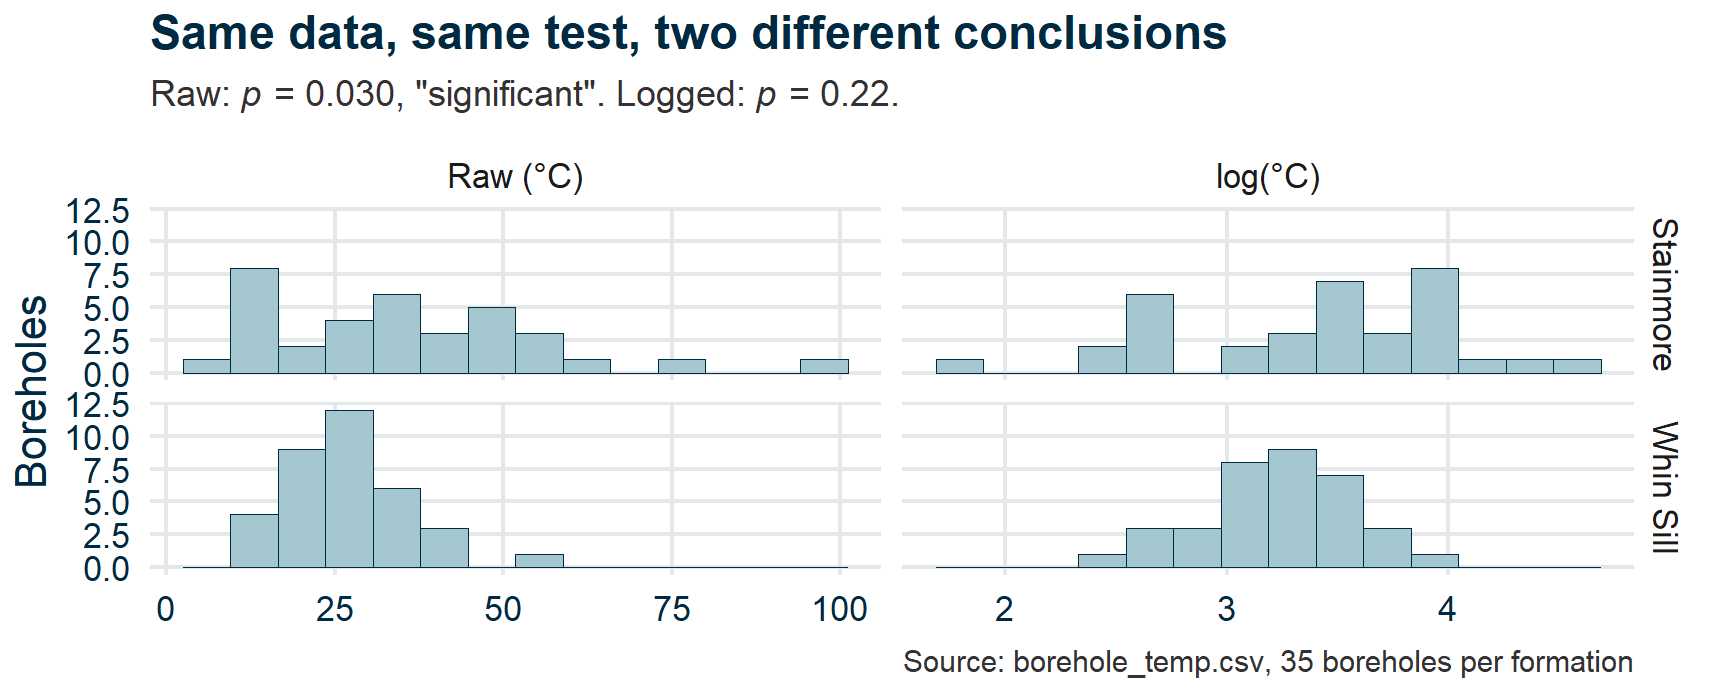
Four histograms of borehole temperature: two formations by rows, raw and log-transformed by columns. Raw, Stainmore trails a long right tail out to 100 degrees while Whin Sill is compact. On the log scale both are near-symmetric and sit almost on top of one another.

HolmesCo made the same mistake

“Geological Solutions Since 2019”

Statistical Analysis — Soil Permeability

t-test on raw values: p = 0.04 → “Significant difference!”

t-test on log-transformed values: p = 0.23 → “No significant difference.”

The “significant” result was an artefact of skewness.

Check your assumptions

  • Recap
  • The null world
  • Interpret a t-test
  • Assumptions

✏️💻 Exercise 2

  • The base rate fallacy
  • Plan your test
  • Wrap-up

In WebR

Given a dataset:

  1. Make histograms of each group
  2. Decide whether to transform
  3. Run t.test() before and after transformation
  4. Compare: did the conclusion change?

Attendance

The base rate fallacy

  • Recap
  • The null world
  • Interpret a t-test
  • Assumptions
  • Check your assumptions

🎓💬 Concept block 3

  • Plan your test
  • Wrap-up

The most important 25 minutes of the course

I’m going to show you why a statistically significant result can still be wrong most of the time.

Warm-up: Monty Hall

Some of you simulated the Monty Hall problem in first-year Python.

Switching wins 2/3 of the time. But your gut says 50/50.

Why? Because your gut ignores the information the host gave you when they opened a door.

That confusion — between P(win) and P(win | what you now know) — is exactly what this block is about.

The medical test

A disease affects 1 in 1,000 people.

A test is 99% accurate (99% sensitivity, 99% specificity).

You test positive.

What’s the probability you have the disease?

Cast your vote

PollEv.com/geol

text geol to 07480 781235

The arithmetic

Out of 100,000 people:

Has disease No disease Total
Test positive 99 999 1,098
Test negative 1 98,901 98,902
Total 100 99,900 100,000

P(disease | positive) = 99 / 1,098 ≈ 9%

Not 99%. Nine percent.

Why is it so low?

Because the disease is rare.

The base rate matters enormously.
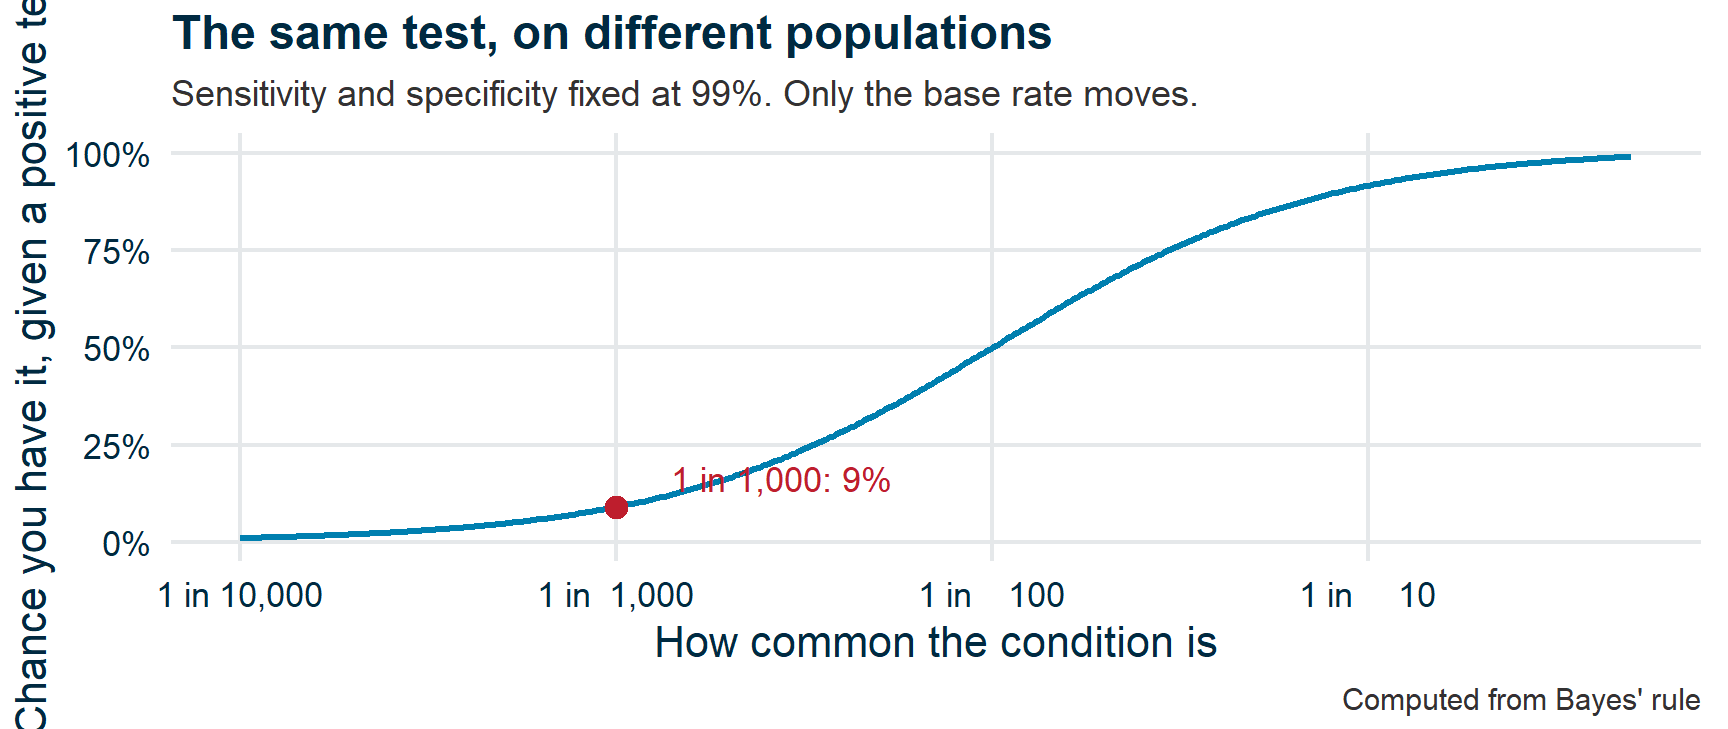
A curve of the chance you have a condition given a positive test, against how common the condition is, for a test that is 99% accurate. It runs from about 1% at one in ten thousand, through a marked point at 9% for one in a thousand, to near 100% for common conditions.

Even a very accurate test produces many false positives when the condition is uncommon.

HolmesCo strikes gold

“Geological Solutions Since 2019”

Press Release — Major Gold Discovery in County Durham!

“Our geochemical assay (95% accuracy) detected gold in 50 out of 10,000 soil samples. Confirmed multi-element anomaly!”

The reality

Suppose 5 in 10,000 samples are actually gold-bearing.

Gold present No gold Total
Assay positive ~5 ~500 ~505
Assay negative ~0 ~9,495 ~9,495

HolmesCo’s 50 positives? Almost certainly all false.

The press release is nonsense.

Connection to p-values

A p-value tells you: P(data | H₀)

How surprising is this data if the null is true?

What you actually want: P(H₀ | data)

How likely is the null to be true given this data?

These are not the same thing. The difference depends on the base rate.

The new refrain

“How plausible was this before we tested?”

Plan your test

  • Recap
  • The null world
  • Interpret a t-test
  • Assumptions
  • Check your assumptions
  • The base rate fallacy

✏️ Integrative exercise

  • Wrap-up

For your project

Discuss with your group:

  1. What comparison will you test?
  2. What’s your null hypothesis?
  3. What’s your prior expectation — plausible or a long shot?
  4. What assumptions should you check?

Write 3–4 sentences.

Wrap-up

  • Recap
  • The null world
  • Interpret a t-test
  • Assumptions
  • Check your assumptions
  • The base rate fallacy
  • Plan your test

Key points

  1. A t-test compares two groups — but check the assumptions first
  2. A p-value is P(data | H₀), not P(H₀ | data)
  3. The base rate determines whether a “significant” result is real
  4. Always ask: “How plausible was this before I tested?”

Exit ticket

A t-test comparing two groups returns p = 0.04. Which statement is correct?

PollEv.com/geol

text geol to 07480 781235

Any questions we missed?

Submit questions:

PollEv.com/geol

text geol to 07480 781235

Next time

Application session: “First tests”

You’ll run your first real tests on your project data.

Remember: a significant p-value is the start of the conversation, not the end.